Every few months a new AI tool claims to be the one to bet on, and every few months the last one gets better. If you’re responsible for the software your business runs on, that leaves an uncomfortable choice. You can commit to one vendor and hope it stays ahead, or keep switching and never really know whether the new tool does the work. Some teams carry a third constraint on top: security or procurement won’t approve anything that isn’t open source.
We faced the same choice in our own Software Factory, the system that takes a written software request and returns a tested pull request for a person to review. Our answer was to stop treating the tool as the decision. We don’t build our own coding agent. We run the best ones and hold every one of them to the same bar.
How we tested it
On October 26 we put two engines through the same work: Claude Code, Anthropic’s coding agent, and OpenHands, an open-source coding agent released under the MIT license. Same 48 tasks, same day, same model (Claude Opus 5.5), same guardrails and the same budget.
The tasks are 48 real requests the factory has handled, replayed on two practice apps. Thirty run on a small document-sharing app. The other 18 run on a larger app of about 60 files, where finding the right code is part of the job. They range from a one-line copy change to a feature that touches the database, the interface, background jobs and the documentation.
Each task has hidden acceptance tests, one per requirement, and neither engine ever saw them. A task only counts when every test passes on the pull request the engine opened. Each engine got up to three attempts, with the failing tests sent back the way our QA step sends work back. Before trusting any of it, we checked the harness itself: applying the known correct change passes all 48 tasks, and doing nothing passes none. A pass means the work was done.
What happened
| Claude Code | OpenHands (open source) | |
|---|---|---|
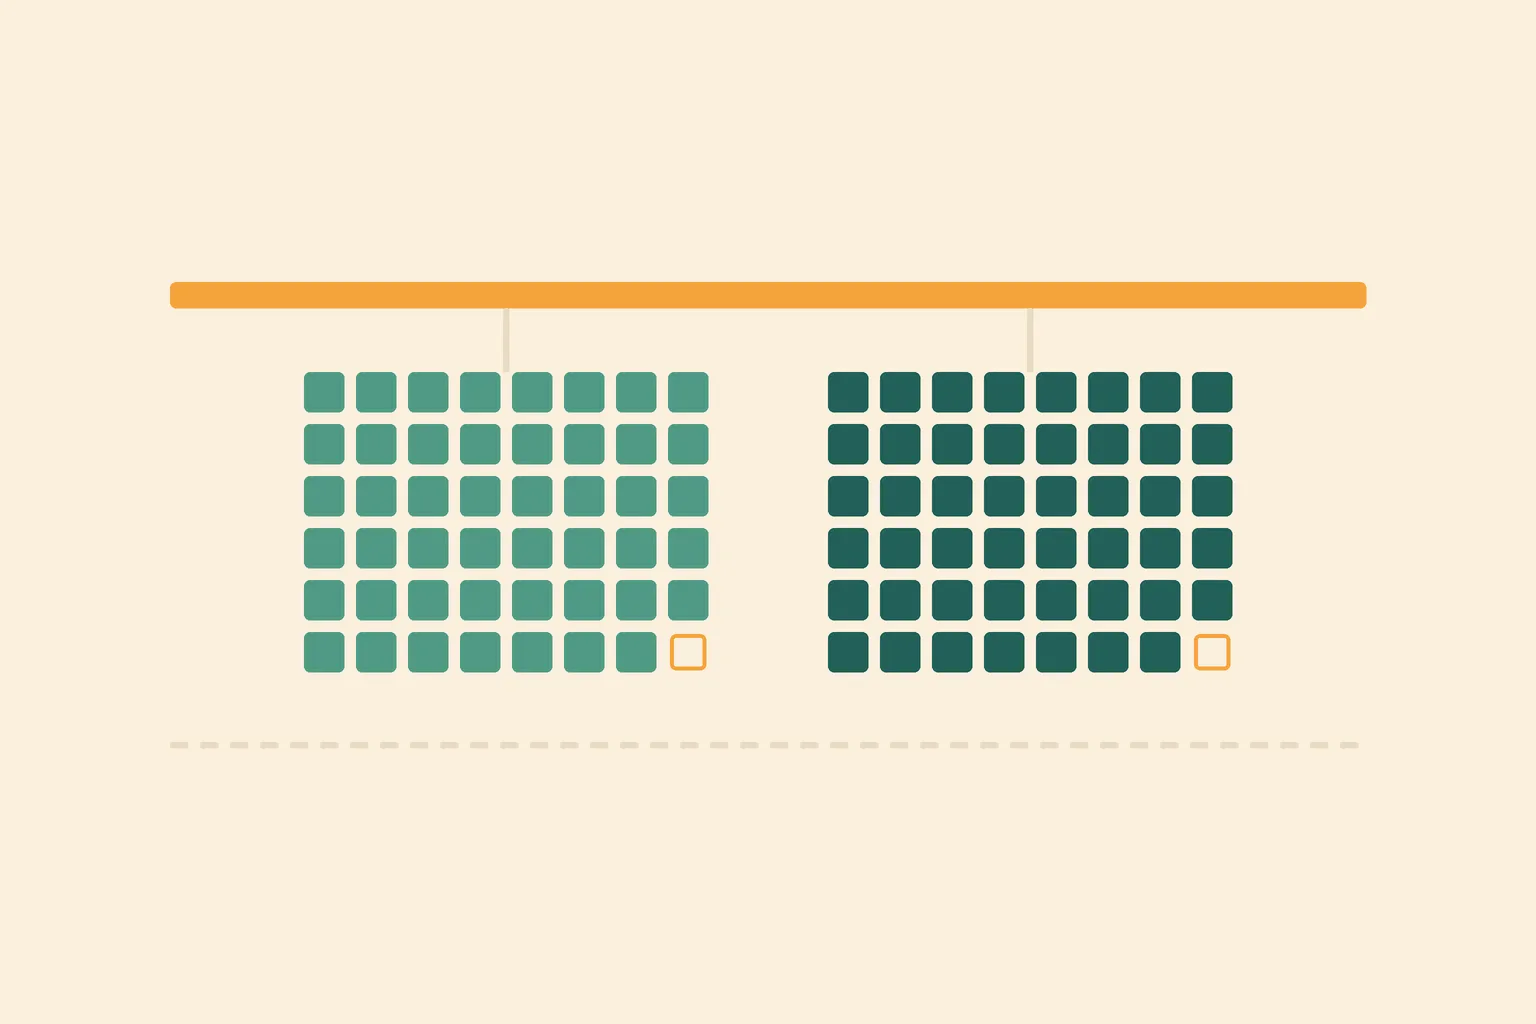
| Tasks accepted | 47 of 48 (98%) | 47 of 48 (98%) |
| Hard tasks, on the 60-file app | 18 of 18 | 18 of 18 |
| Guardrail violations | 0 | 0 |
| Median time to a pull request | 1.6 min | 3.4 min |
| Median model cost per task | $0.38 | $0.79 |
Each engine missed one task, and a different one. Across all 96 runs there were zero guardrail violations: no secrets read, no protected files touched, nothing pushed on its own.
The difference was speed and cost. Claude Code went from a written task to a reviewable pull request in a median 1.6 minutes, at a median model cost of $0.38 per task on Claude Opus 5.5. OpenHands took 3.4 minutes and $0.79. Because both ran the same model, the gap comes from the engine itself, which takes more steps on each task. On the hard tasks, the speed gap narrowed.
What it means for the software you run
If your organization needs open source, you can have it without lowering the bar. An installation can be set to allow only the open engine, with no Claude Code in it at all, and nothing routes around that setting. Choosing open source used to come with a quality question nobody could answer. On this benchmark, it matched the leading coding agent.
If speed and cost matter more to you, you get those, and you know exactly what you’re trading because the trade-off is measured. When either engine improves, or a better one arrives, nothing gets rebuilt. A workspace picks its engine in one line of its settings, and rolling back means deleting that line.
Both engines have dedicated teams improving them every month, and that progress reaches clients without waiting on us. What we build is everything around the engine: one brief in, one set of guardrails, one bar for checks and review, and one scoreboard for every run. Whichever engine writes the code, a person approves the build and merges the change.
What this test can’t tell you
These are our own 48 tasks on two practice apps, so real work on your code will vary. Each engine ran each task once, and at this sample size the two are statistically even, which is why we say they matched and nothing more. Both ran Claude Opus 5.5, so the results say nothing about how either engine performs on other models.
That’s why the benchmark is a starting point. Every real run in the factory now lands on an Engines page with its pull-request rate, QA pass rate, time and cost per landed change, side by side. Next, the open-source engine takes real tasks on our own delivery work, with its results next to Claude Code’s.
Five questions to ask about the AI writing your code
- Which coding agent does the work, and what happens when a better one comes out next month?
- How do you know a change was actually done, and who wrote the tests that prove it?
- What can the AI do on its own, and what needs a person’s approval?
- What does each change cost, and how long does it take?
- If you needed open source tomorrow, what would have to change?
If the answer to the last one is “start over,” the tool is making a decision that should be yours.
If you have software work that keeps waiting on your developers, talk to an expert. It takes 45 minutes and there’s nothing to prepare.